
Machine Learning for Anomaly Detection: Methods, Use Cases, and Best Practices
Summarize and save time
If we are going to discuss anomaly detection in this blog, one obvious question that needs to be answered on priority is, “Why does anomaly detection matter?”
Modern-day businesses generate an extensive amount of data constantly, some of which add value and insights for present and future actions. Data can be structured or unstructured in the form of transactions, network events, user activity, sensor readings, application logs, customer interactions, medical records, or operational metrics. Each second produces a large amount of data, each of which reflects normal activities.
Out of this, there is a small portion of data that can indicate something valuable, like fraudulent transactions, a cybersecurity attack, equipment failure, unauthorized access attempts, data quality issues, system breakdown, unusual customer behavior, bad customer experience, and so on.
To locate, trace, and evaluate these events manually can be complicated. Traditional rule-based systems can be helpful but only to a limited extent because they operate on predefined assumptions. Working on a fixed set of rules can’t work because user behavior keeps changing, and so do the data and risks.
That’s where machine learning for anomaly detection becomes valuable. Machine learning models don’t operate on rigid rules, but they learn patterns from historical or real-time data and identify any unusual patterns or false alerts that are distinct from the expected behavior. These systems consider context, timing, relationships, frequency, and behavior changes across multiple variables. Anomaly detection using ML assists in finding errors as well as signals that deserve attention.
The use of machine learning models for anomaly detection is widespread across industries like banking, manufacturing, retail, security, hospitals, eCommerce, and so on. AI app development companies like Prakash Software Solutions Pvt. Ltd. (PSSPL) have a team of 250+ AI/ML engineers who have the expertise to design and deploy enterprise-grade AI solutions across distinct global industries. Partner with us to experience our end-to-end AI development services using cutting-edge AI technologies.
Machine Learning for Anomaly Detection: Statistics and Market Outlook
With the growing use and management of connected systems, cybersecurity threats, and financial transactions, the demand for anomaly detection is rising to gain real-time data insights.
- According to September 2026 reports from Fortune Business Insights, the global anomaly detection market size is expected to grow at a CAGR of 16.7% from USD 8.15 billion in 2026 to USD 28.15 billion by 2034.
- The survey data on AI for cybersecurity reveals that 77% of organizations have adopted AI for cybersecurity, with a leading focus on anomaly and phishing detection.
- Artificial Intelligence and Machine Learning dominate the technology segment with a market share of approximately 59%.
The use of AI-facilitated anomaly detection is rapidly gaining traction across healthcare, manufacturing, banking, cybersecurity, telecommunications, and retail sectors. This demand is because of the growing demand for intelligent monitoring systems that can handle, process, and monitor large volumes of data constantly.
Anomaly Detection Explained in Detail
Anomaly detection in simple terms is the process of identifying data points, user behavior, and buying patterns that differ from what is labelled as normal. Many times, people often believe that an anomaly essentially implies something wrong. But that’s not true because it can indicate valuable observations that deserve your attention or further investigation.
An anomaly can range from a simple unusual event to a changing relationship between distinct variables, or a sudden change in the usual data distribution pattern. A simple example of an unusual task is a sudden spike in website traffic that indicates to be the result of a successful marketing campaign or bot marketing.
Machine learning for anomaly detection ensures that the system understands the context before flagging any event as important. Let’s understand in further detail how machine learning helps to detect this.
How Machine Learning Detects Anomalies?
Imagine a team setting where you are the manager. Before you introduce any change in your team’s working policies and goals, it’s important to discuss it with your team, flag the pressing issues, and then introduce improvements or changes in the working patterns.
Likewise, before machine learning for anomaly detection suggests any changes, machine learning detects the normal user behavior and then measures how the new observations differ from that pattern. This is what a typical anomaly detection workflow using a machine learning model includes:
Defining the Business Problem
The first and foremost step in anomaly detection is to determine what needs to be detected. The algorithm decision comes at a much later stage. Some of the possible objectives that are mapped out in this phase include fraudulent transactions, possible equipment failures, product defects, network issues, strange customer behavior, and so on. Determining the objective helps to define the model, data, alert strategy, and evaluation criteria.
Gathering Relevant Data
Business data keeps flowing, and it can come from various sources, including:
- Application logs
- IoT sensors
- Medical devices and data pipelines
- Security systems
- CRM and customer records
- Cloud infrastructure and user activities
For anomaly detection, it’s very important to collect data from the right sources at the right frequency and identify the right context for the model to interpret user behavior. At PSSPL, our team of AI/ML engineers is well-trained and competent in putting relevant and reliable business data to valuable use.
Cleaning and Structuring the Data
Since data comes from multiple sources and is dispersed across several locations in the organization, it’s vital to clean and properly structure the data before utilizing it. This basically refers to the stage of data preparation, because poor data can result in false alarms, misleading assumptions, and missed anomalies.
Some data preparation strategies include:
- Elimination of duplicated records
- Creating useful features
- Filtering known errors
- Handling numeric variables and missing values
- Removing sensitive information wherever it’s inappropriately placed
Establishing Normal Behavior
Like a baseline foundation lays the roadmap for your development journey, a baseline is required for the machine learning model as well. This can be learned from customer segments, network behavior, historic data, approved business rules, equipment conditions, evolving cyber threats, and so on.
Scoring the New Observations
The new events that occur in the pipeline are assigned a score by the machine learning model, which is popularly referred to as the anomaly score. A high score indicates a significant variation of the event from the learned or normal patterns.
Scoring is based on similarity in behavior, forecasting errors, probability, deviation in sequence, reconstruction errors, and so on.
Sending Alerts or Actions
It’s not a defined rule that every anomaly detection will trigger an urgent alert or a consecutive action. The events are classified based on their level of severity as low priority, high risk, informational, critical, or ones that require review.
These alerts must indicate context, such as the affected customers, systems, transactions, devices, or business segments.
Incorporating Feedback
Despite technology doing its work precisely, it can’t replace the accuracy of human feedback. Human investigators also become essential because they can label alerts as true anomalies, false positives, expected exceptions, new patterns, or known issues.
After all, machine learning for anomaly detection is a technological advancement with its downsides, as humans do. This human feedback can assist in improving thresholds, retraining, and prioritizing future anomalies.
Types of Anomalies
There are distinct types of anomalies in a modern-day business environment, and understanding each one of them helps determine the best approach. Let's understand some of the most common anomaly types with examples.
| Type of Anomaly | What It Means | Examples |
|---|---|---|
| Point Anomalies | Point anomalies refer to a single observation that greatly differs from the remaining set of data. These are often considered well-suited for statistical methods or threshold-based approaches. | A sudden surge in the server's CPU usage or multiple failed login attempts. |
| Contextual Anomalies | Contextual anomalies are regarded as unusual only within a specific context. The feature requirements for this type of anomaly include time, location, customer segment, environment, and operating state. | High website traffic during hours when the traffic volume is normally low. |
| Collective Anomalies | Collective anomalies, as the name suggests, refer to a group of observations that become unusual when taken together. This type of anomaly usually requires time-series analysis, sequence models, and advanced behavioral modeling. | Fraud indication based on a sequence of small, unusual payments or gradual equipment failure. |
| Global and Local Anomalies | A global anomaly differs from the entire dataset, whereas a local anomaly differs from its surrounding neighborhood but is not unusual globally. | For instance, a customer's order value, if compared globally, might appear normal but can be unusual when compared locally with similar customers in the region. |
Machine Learning Models and Algorithms
When looking for machine learning models for anomaly detection, there are distinct types of models. Each one is suited to a different data condition, type of anomaly, and business needs.
Let’s look at some of the well-regarded machine learning models:
(1) Statistical Methods
When it comes to statistical methods, a combination of averages, distributions, variances, z-scores, and control charts is used for identifying unusual observations. The new data point is compared with previous behavior patterns or the expected behavior to flag anomalies that fall outside of the acceptable range.
This method is best suited for:
- Monitoring financial transactions to screen for fraud.
- Monitoring websites, applications, and infrastructure performance.
- Monitoring sensor-based equipment.
(2) Local Outlier Factor
Local Outlier Factor is an ML model that compares the density of a specific data point with that of its neighbors. This is useful for identifying unusual observations within their local context. In the case of very large datasets, this model can be computationally expensive.
It’s a well-suited method for:
- Customer behavior
- Clustered datasets
- Segmented users or transaction activities
(3) Isolation Forest
Using the Isolation Forest model, anomalies are detected through data partitioning. This model helps to quickly and easily isolate unusual observations from normal ones. With a greater degree of efficiency, this model doesn’t require a large number of labeled anomalies.
It’s well-suited for:
- Monitoring user behavior
- Detecting fraud
- Analyzing high-dimensional data
- Operational metrics
(4) Clustering-Based Methods
Clustering algorithms are used to group similar observations into one when the data contains natural groups. Clusters require careful interpretation using common approaches like HDBSCAN, DBSCAN, K-means, and so on.
Best-suited for:
- Unsupervised exploration
- Customer segmentation
- Network behavior analysis
(5) One-Class Support Vector Machines
One-Class SVM learns and sets a boundary around normal observations. As a result, new observations beyond this boundary are treated as potential anomalies. With the need for careful parameter tuning, this machine learning model might not be suitable for large-scale streaming environments.
Best-suited for:
- High-dimensional data
- Small datasets
- Cases with availability of normal examples but limited anomaly labels
(6) Autoencoders
Autoencoders refer to neural networks that learn to reconstruct the input data and therefore require more data, resources, and expertise compared to simple algorithms. If trained mainly on normal examples, these models tend to give higher reconstruction errors for unusual observations.
Best-suited for:
- Sensor data
- Images
- Complex and high-dimensional data
- Behavioral patterns
(7) LSTM and Other Sequence Models
Long Short-Term Memory networks and other sequence models learn patterns across time. They identify each instance when a sequence deviates from an expected behavior.
Best-suited for:
- Patient and equipment monitoring
- Application performance
- Network activity
- User sessions
(8) Random Cut Forest
This model is designed for identifying unusual points in high-dimensional data or streaming. It’s best suited for instances of real-time monitoring of metrics and transactions.
(9) Forecasting-Based Models
Just like the name suggests, these models predict what’s coming next, and the difference between the prediction and the actual observation becomes an anomaly signal.
Best-suited for:
- Inventory demand
- Revenue monitoring
- Website traffic
- Financial time series
(10) Ensemble Models
An ensemble model combines several detection approaches to improve reliability. But it requires more design, explainability, and calibration efforts.
Machine Learning for Anomaly Detection Industry Use Cases
Startups and enterprises utilize machine learning for anomaly detection, detecting unusual behavior across networks, equipment, transactions, customer activities, and operational data. The application of these models varies from industry to industry, but the end goal of detecting meaningful deviations, reducing risks, and enabling faster responses stays the same.
Let’s look at the industry-wide use cases of machine learning models:
Cybersecurity
Anomaly detection is popularly used among cybersecurity teams for monitoring network traffic, cloud configurations, user behavior, authentication patterns, volume of data transfer, and endpoint activity.
Banking and Finance
In the banking and finance industry, anomaly detection is used for identifying irregularities in claims, money laundering indicators, unusual spending patterns, attempts of account takeover, and suspicious login behavior.
Healthcare
Healthcare systems require strong and reliable anomaly detection because false alerts can result in serious risks and overwhelm doctors, clinicians, and hospital staff. Healthcare anomaly detection supports analysis of medical images, equipment monitoring, alerts for patient monitoring, analysis of fraud, and clinical data quality checks.
Manufacturing
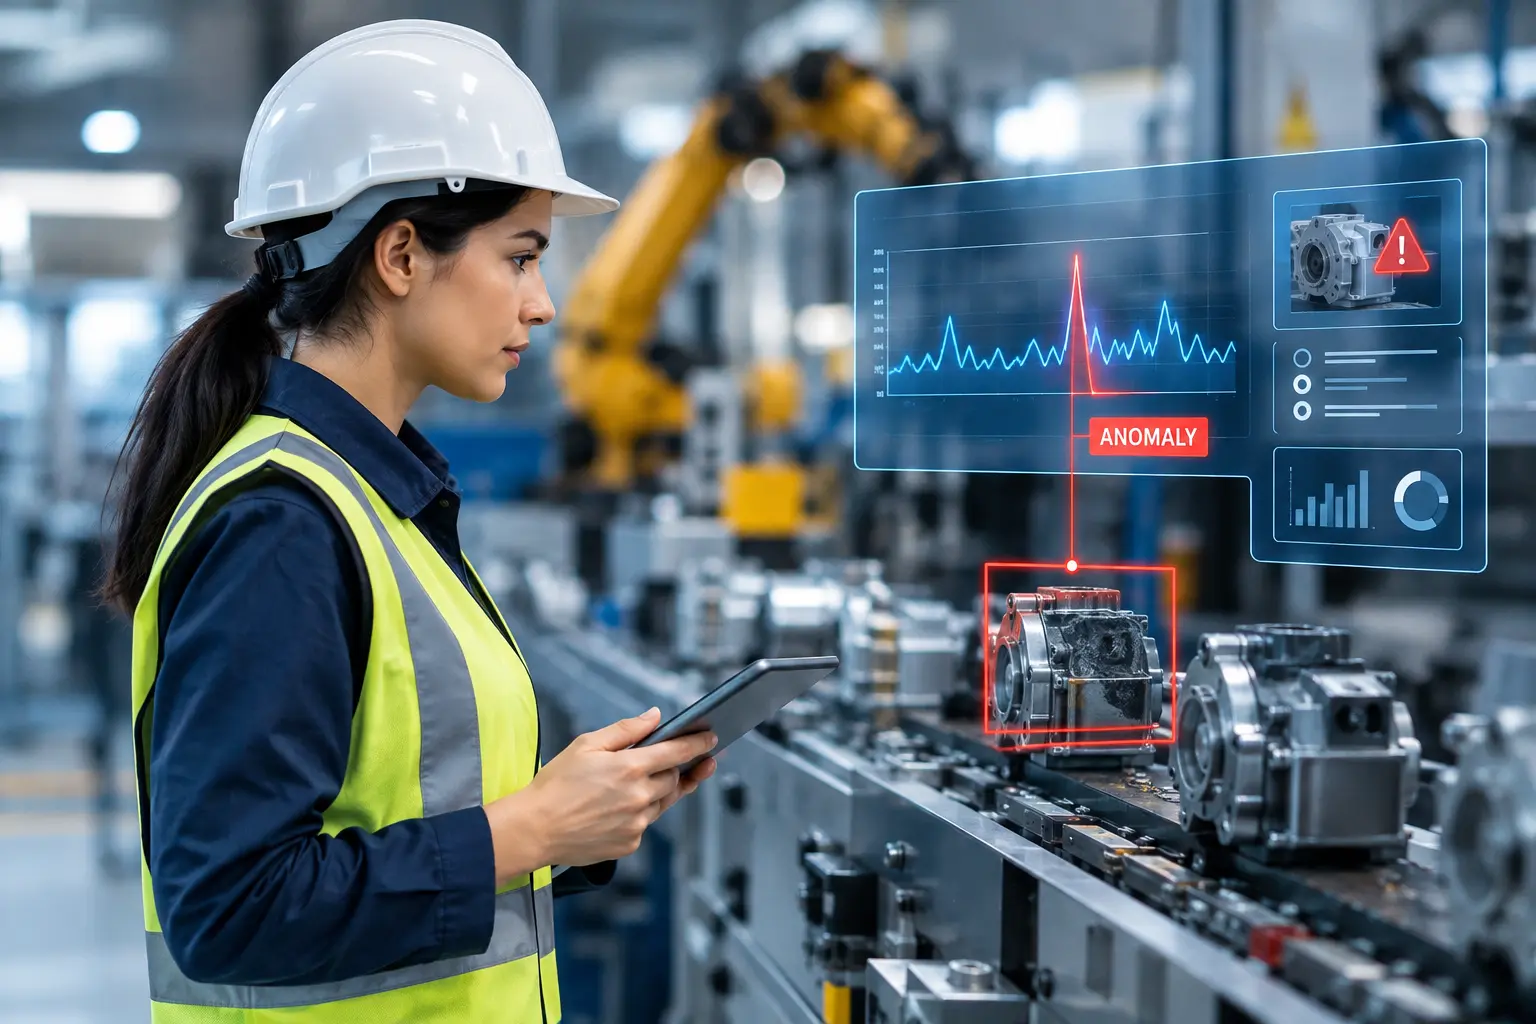
Manufacturers utilize machine learning for anomaly detection to detect gradual changes and anomalies in vibration, temperature, sound, and pressure before the machine fails. This allows the teams to plan maintenance ahead of time and minimize the possibility of downtime.
In the manufacturing industry, anomaly detection is used for quality inspection, predictive maintenance, sensor analysis, supply chain management, worker safety, and production-line monitoring.
Telecommunications
In the telecommunications industry, machine learning for anomaly detection can help identify degradation and prevent it from becoming a widespread customer-impacting incident. Telecommunications providers utilize machine learning models for monitoring call drops, fluctuations in network performance, service outages, equipment functioning, and traffic spikes.
Cloud and IoT Operations
AIOps teams utilize machine learning for anomaly detection to detect problems in infrastructure capacity, memory leaks, deployment issues, rates of abnormal errors, service anomalies, and CPU spikes.
Retail and eCommerce
Anomaly detection is largely used among retailers for detecting demand changes, account takeover, payment failures, returns fraud, pricing errors, unusual purchase behavior, demand fluctuations, and inventory discrepancies. For instance, machine learning models can help retailers distinguish seasonal demand from unexpected behavior by using promotions, customer segmentation, and product categories.
Data Quality and Pipeline Monitoring
Early detection of anomalies by data teams helps safeguard reports, dashboards, AI models, and downstream decisions. Anomaly detection is used for identifying schema changes, unexpected null rates, duplicated records, pipeline delays, missing partitions, and unusual metric values.
Real-World Applications of Machine Learning for Anomaly Detection
It’s easy to spread the word of advice and educate readers about technology, but putting it into practical use is where the real challenge comes arises. That’s exactly where companies like us carve the distinction. At PSSPL, we back our claim of software engineering excellence with a proven track record of implementing our enterprise-grade AI systems for substantial business ROI.
The following PSSPL case studies will give you an idea of how our team of experts designed and deployed machine learning models for identifying unusual patterns, preventing anomalies, and improving monitoring.
Smart Forgery Detection for Insurance Claims
One of our property and insurance clients was annually processing 2 million+ digital claims. Customers had the flexibility of submitting damage photographs through their mobile applications, which increased the risk of edited, reused, or AI-generated images being submitted to enter and process the insurance claims.
To deal with this challenge, the PSSPL team of AI/ML experts designed a smart forgery detection portal that worked as a security layer before claims reached the core claims system. This solution facilitated an analysis of image structure, metadata, copy-paste edits, hidden inconsistencies, and other suspicious patterns that indicated manipulated photographs.
This portal also included a live dashboard that helped the analysts review flagged images, investigate areas of suspicion, and access a start-to-end audit history for each scan. The outcomes of implementing this solution include:
- A 95% reduction in the time taken for manual inspection of suspicious images.
- 100% prevention of altered or edited images entering the claims process.
- A complete audit trail to track each image assessment.
- Less than 1 second average image scanning time.
Read the complete case study: A Smart Forgery Detection Portal for Insurance Claims Processing
Scalable Video Inspection for Automotive Compliance
One of our automotive software providers was struggling with a review of 50,000+ inspection videos every day across its network of independent dealerships and franchise locations. As usage increased, the high-definition uploads affected the speed of compliance and quality scoring and resulted in processing delays.
That’s when PSSPL redesigned the platform’s video intake and processing architecture with Python and FastAPI. The upgraded system helped identify quality and compliance issues across the extensive volumes of video data while maintaining secure separation between the dealership groups.
The solution helped achieve:
- 40% reduction in the cloud cost per video.
- 500% improvement in the concurrent video processing capacity.
- Onboarding 1,000+ locations in one quarter.
- Sub-50-millisecond average response time for the web portal.
Read the complete case study: Scalable Video Inspection for Automotive Compliance
Looking for the right anomaly detection use case for your business?
Machine learning for anomaly detection has a vast array of use cases, from fraud detection and predictive maintenance to cybersecurity, product monitoring, and data quality. At PSSPL, we assist startups and enterprises in evaluating their data readiness, identifying high-value use cases, and choosing machine learning models that align with your operational workflows and business requirements.
How To Build an Effective Anomaly Detection System?
Building an effective anomaly detection system is not simply about choosing the machine learning algorithm. It’s more than that, involving a definition of what ‘normal’ means for your business, selecting the right model, preparing the data, and connecting the detection results to a clear response workflow.
Here are a few specifics that can help you build an effective anomaly detection system with the right machine learning models:
- Define what normal behavior is for your business, as a model can’t differentiate between unusual and normal behavior without that understanding.
- Choose the right data frequency that matches the business decision and engineer the right context with the following features:
- Location
- Customer segmentation
- Time of day
- Day of week
- Season
- Device type
- Account age
- Product category
- Historical behavior
- Choose between supervised and unsupervised learning. Supervised learning utilizes labelled examples of normal and unusual behavior. Unsupervised learning identifies patterns without the need for complete anomaly labels.
- Carefully define and set alert thresholds based on customer impact, business risk, severity, and investigation capability.
- The anomaly alert needs to be connected to an action to make the detection valuable. Make sure the system does the following:
- Explain the reason for the event being flagged.
- Recommend the next steps.
- Assigns priority.
- Provide supporting evidence.
- Escalate to human agents when necessary.
- Monitors the performance of the chosen machine learning model to identify missing features, new data sources, shifts in user behavior, changes in alert outcomes, and changes in feature distribution.
Why Partner with PSSPL for Anomaly Detection?
Prakash Software Solutions Pvt. Ltd. (PSSPL) is a leading AI app development company with a team of experts who excel in machine learning, computer vision, natural language processing, data engineering, predictive analytics, and MLOps services.
We provide end-to-end support in the anomaly detection lifecycle by using advanced tools and platforms like Python, TensorFlow, PyTorch, Google Vertex AI, Docker, Kubernetes, MLflow, and scikit-learn. The PSSPL team of experts has extensive experience in anomaly detection across various industries, offering the following services:
- Discovery of the business problem
- Data collection and preprocessing
- Algorithm selection
- Feature engineering
- Model development and testing
- Model monitoring and retraining
- Governance and security
- Ongoing monitoring and optimization
Frequently Asked Questions (FAQs)
Machine learning for anomaly detection utilizes algorithms for learning normal data patterns and identifying events that are distinct from those patterns. It is widely used for fraud detection, predictive maintenance, cybersecurity, data quality monitoring, and operational risk detection.
There are distinct types of machine learning models used for anomaly detection. The best model depends on the data type, scale, anomaly type, and response requirements. Common machine learning models include:
- Isolation Forest
- Local Outlier Factor
- One-Class SVM
- Clustering algorithms
- LSTM networks
- Autoencoders
- Random Cut Forest
- Forecasting models
- Ensemble methods
Yes, real-time anomaly detection helps process streaming transactions, network events, application logs, sensor readings, and user activities.
Yes, small businesses or startups can begin with a focused use case such as account security, payment anomalies, website monitoring, equipment health, etc.
False positives can be reduced in anomaly detection with contextual features, feedback loops, alert prioritization, and combining multiple machine learning models.
Final Thoughts
Machine learning for anomaly detection empowers organizations in identifying unusual behavior across systems, transactions, equipment, networks, customer activities, and data pipelines. For delivering value, it’s not necessary to label every unusual event as a problem; what matters is identifying the important events, explaining why they are important, and connecting them to an appropriate response.
Anomaly detection has to be carefully and strategically designed around the business decision that follows alerts. Convert raw data into an early-warning system by choosing the right machine learning models with reputed app development companies like Prakash Software Solutions Pvt. Ltd. (PSSPL).
I have managed SEO and digital campaigns in several industries, but the industries that have really benefited have one thing in common; the traffic we are driving is the right traffic, and each rupee spent relates to an actual business goal. It is easy to rank for a keyword and get clicks, but the challenge comes in when we need to ensure that these visits convert, and the team knows from which medium the visit came. It is here where most "set and forget" campaigns fail, and it is here where we concentrate most of our efforts.